yesterday i was talking to some friends and made a prediction “2.The buzz on AI-based security threats might turn back the clock on cloud and always-connected computing, in novel ways.”.
Only to realize that October is turning out to months of hacks and security breaches.
The post mythos era ,where AI labs trained their models on data related to security vulnerabilities(should they have?) allows any random person to point it at software systems and enginner a hack .We can call it hacking tools for everyone era.
Of course systems will be patched up at rapid pace and at mass scale.
but this is also leading to a systemic shift.
A software running somewhere is now our weakness. and
A software running over Internet/network is our biggest weakness.
You might call this very anti software or anti internet take; but soon we will be entering era of questioning cloud computing ,always on, excessively connected software ( and hardware) systems.
That doesnt mean computer science or network and classical security theories are accepting defeat !
but now they need to go back to drawing board and rethink it all.
and hence “2. The buzz on AI-based security threats might turn back the clock on cloud and always-connected computing, in novel ways.“
Coning new term for psychological state of a human being while working with AI led coding agents.
This is gen beta successor to a gen Z term ,doom scrolling .
Definition :Promptxiety represents the elevated levels of anxiety that a sincere and quality conscious engineer experiences after he/she fires a prompt on his coding agent/s and tries to makes sense of all the responses the ai agents gives him and the heightened built up anticipation,often unknown to him/her that might involves holding his/her breath ,around what the final outcome is and whether it will actually be what he/she asked for or does he/she have to then spend another hour/s figuring out whether and how agent got it wrong and how he/she will then correct it, while everyone around him thinks he/she is having easy life due to the agent doing all the work and having a cool life… huh
Backstory: a few months back, I wrote a blog post on how agents, then called chatbots, used to be defined: https://sachindixit.co.in/2025/12/05/chatbots-before-llms/. This was supposed to be followed by a detailed post on how agent creation has evolved since then.
In the meantime, agents became a buzz and faded a bit 🙂 I also started teaching our engineers about it, presented them at different meetups and conducted workshops. That evolved into a neat code repo with a do-it-yourself agent course. I also had a separate repo with my notes in textbook style on what the concepts meant. Now I have merged them together and am making it public.
As an author, I find it useful, but I must say the field is evolving fast; there is a lot to be added in the textbook. Moreover, the prose is my opinionated take on agentic everything; the code/concept ladder represents how I would teach concepts from the ground up. So have a look, and I hope it helps you .
In the early era of social network there was all kind of pressure on social media companies to show number of active users and engagement matrices.So companies resorted to virality and reaction.
Its not that technology or AI in that era couldn’t give them means to put qualitative filter but lets give them benefit of doubt that challenges existed.
But now ? Now LLMs have proven that one can do all sort of dissection around quality on all types of content, that too at scale.
And there we have LinkedIn suggesting us posts that are viral in your community, geography or topic.
The irony is that some of worlds greatest scientist , professor and professional people exist on LinkedIn, still !
Its totally possible for LinkedIn to deepen the definition of relevance , quality , impact and sell that to advertiser.
Instead of borrowing tiwtter and instagram playbook of viraliry, engement and upsell.
What is the formula for a blockbuster Bollywood movie?
If you are a traditionalist, the answer might be: hire a superstar pair of leading hero and heroine, amazing music and lots of marketing buzz. Gets you a 100 Cr opening. If you are inspired by OTT movements, the answer might be: get a good script, hire good actors, and by the way it’s good if they are also superstars and throw in some good music. If you are a trendsetter, then you might say: a relatable script, a great storyteller director, lots of good actors -even for smaller roles- music that flows with the theme of the movie and get amazing technicians on sound, lights, editing, action and props.
Now pls come to the buzz we hear on how development teams should shape up in the era of AI generated code: Some say we need more expert generalists, some say have 2-person pods, some the difference between roles has vanished and everyone is a product engineer now, some say freshers have no future, some say you don’t even need teams now -just have multi-agent goal loops.
The fun part is that all of these are possibilities. The business that gets hard cash relies on the outcome, not the team topologies.
But what happens when the whole business is about selling tools for software development? A singular outcome -that works well for the strength of the tool being sold but hides its flaws and assumes a certain density of talent-motivation-remuneration.
That is a talent agency telling you how to make a blockbuster movie! It is even lining up relevant experts to convince you about it.
So, AI-generated code is a good accelerator, but there are many ways to structure your setup and get the best software for your business.
There is a definite case for everyone to reflect on theirs; but to give advice assuming everyone is a Valley-based SaaS company that works in the consumer space only, skips enterprise, has no diversity of domain, doesn’t need customization, doesn’t have to catch up to regulations and region diversity, hires only Stanford CTOs and Harvard MBAs as staff, has the means to navigate vendor lock in, is into consulting business and lastly has soverign backing is saying why dont i and you are as fit and goodlooking like bard pitt and tom cruise. Well …..
Guys, the cognitive numbness caused by ChatGPT’s style of documentation and meeting room discussion is here, real and bad ….
I am getting more and more design documents/disucussiosn that now have wording like “here is what it means,” “here is why it matters,” “Instead of this it is that” “five reasons why this is important” “..it is inherently bad at” ” the X has sfhited to Y” …and repeated usage of Goal/Insights/Strategic/Impact and so on….
The experience felt exactly like watching Instagram reels, every other reel uses the same song or music in the story, the plot lines are similar, the visual aspects are in the same vicinity and so on .. The effect Instagram had on me is that it numbed my mind with no focus on what was shown and no significant recall of it. Which is exactly opposite of what our roles at the workplace expect us to do ….
Just to be fair, such words showing up in docs and meetings aren’t a new phenomenon. When Stephen Covey released his books, we suddenly had synergy and win-win showing up in every conversation. The same thing happened to books and talks by Steve Jobs, Jeff Bezos, till your latest Darios and Altmans. But this jarganification of normal conversation happened over a longer timeline. So our brains had time to adapt and adjust.
This ” feel thoughtful without actually thinking about it ” style of narration was useful for social media engagement and payouts. And now, LLMs have pushed it on everyone’s keyboard. Sadly, people are dumping the conceptual rearrangement and problem reframing and discourse dissemination without realizing what it is and what effect it will have.
So the problems of the humanities domain i.e logic, fallacies, rhetoric, synthesis, nuance and so on, are becoming problems of software engineering …
as an engineer with a master’s in humanities am more worried …
Its little surprising that analysts at large aren’t pronouncing it yet .
So Web1 was the advent of the internet(wwb) as we know it . It heralded us into client-server at a worldwide scale . Everything is web-something website/webservice and so on. Browsers were the prime representative. Request-response or search/type was the paradigm.Active/Dynamic content was the currency.
Web 2 was the advent of content networks on the web. It heralded us into a network of content providers . Everything is a social-network something. Contact/Connections and the resultant network onto something were the prime representative. Feed/subscribe, scroll was the paradigm. Post and React was the currency.
Web3 is now the advent of Large Language models. It heralded us into an AI model as a window into the information. Everything is “ask me” something. Chat Windows are the prime representative. Generative Assistant is the paradigm. Questions/Answers, Detailing/Summaries, Ideate/review i.e humanization of the interaction is the currency (Anthromorpization of Internet).
ps: It also plays out accordingly if you study the programming frameworks of the era. The langchain tribe of frameworks has exactly recreated the primitives of the web/J2EE era. ChatGPT has replaced dot com as the representative term 🙂 .
Just to be fair to blockchain guys, it didn’t redefine the basic nature of human interaction with information systems. Analysts hurried to coin the buzzword for what was a different technology implementation of the web 2 style networked interaction model.
Andrej Karpathy published his work on auto research where he used ai to improve itself .
It brought back memory of old project assignment. This was a time when we were hired as interns at Infosys and we had to give this final coding assignment that would make or break or employment .
The project
In this we were given a working C program that would produce certain result already.
Our job was to read this code file via another C program. This new C program that we were to write had to modify the original C code following bunch of rules.
First set of rules wear on formatting; for example if there are multiple variables declared on a same line they should be rearranged so that there is one variable declared each line. Then some variables were declared and initialized in same statement ,some were not.Our job was to rearrange them such that the declarations would occur before the assignment.Again one statement at a time.In case there were multiple variables declared or initialized they had to be separated as one statement per line.
Another rule was that their naming convention.Here we had to find their type and use that as prefixes to the original variable names. Another rule was that these variables would be rearrange in the sequence of their appearance in the code. Similarly we had to rearrange the functions in the sequence of their appearance.
We had to retain any comments or imports at their new relevant positions.I might have forgotten few rules here but you get the idea.
The last step was the eval. Our new program had to compile the modified program and execute the a dot out file and compare the result to original files output.
We felt the presence of auto research
As such the idea of program writing or modifying itself is classic item in computer science. When i/we were doing assignment i got fascinated by that idea.However we didnt have power of LLMs and their long context window with us at that time.So the idea of writing a program to create a sophisticated self improving,self modifying program sounded too acadmic and too cumbersome so i stopped my mental pursuit there*.But now LLLs are here and stimulating self awarenesses and self reference for a program is trivial.So its a fun times for programmers i say..
*yacc/lex and sed/awk was where i took refuge.Thanks to “Archie” mentors.
Been writing small posts on how LLM based coding is evolving and how it will impact the software industry.The posts are aging so well that by Feb 2026 the markets and public are already convinced that LLM coding will make hand crafted code thing of the post.Thanks to anthropics claude releases.Hand crafted code might become an artistic pursuit even or just a teaching tool.
But where is taking us?
The industry : Would benefit a lot , now that we can ship out software faster than before . This also takes the pivot of success back where it always belonged; that is having superior ideas and executing it well till production.
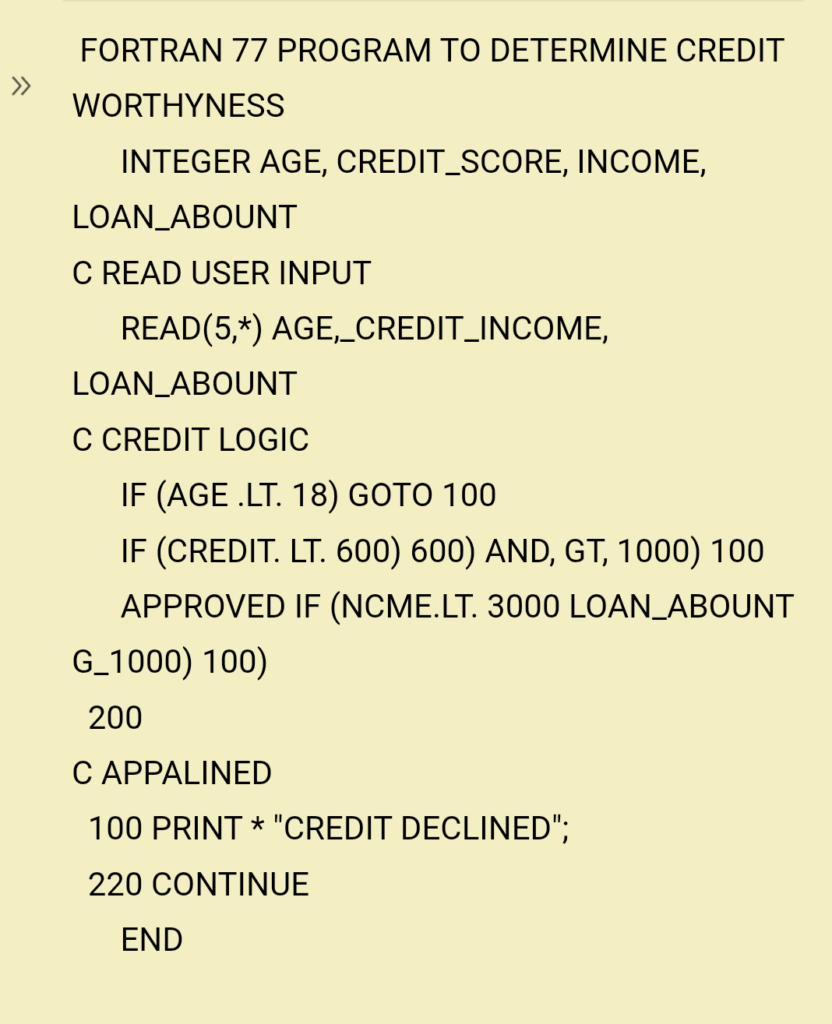
The code : Perfecting creation of structural code is something that LLM based coding approaches have already demonstrated that they can master well.By now people have also demonstrated that even the intentional part code can also be crafted with LLM based coding approaches. That leaves us with only the bare bones part the software,which is the code of business rules. The hard part of business which only we know .The best example of such code i could think of was how fortan programmes were written and used .Just the exact business rules sans the I/O or hardware or framework considerations.
(sample fortran code , generated via , well 😉 AI )
Individuals : The spot where our jobs were standing has shifted now.Instead of being the person who wrote code by understanding business from someone.We now have become the person who understand business so well that we can now use LLM coding approaches to fulfill the effect business needs.This was always why IT department existed in the first place (hence the fortran analogy).Is this making all of us business analysts ,not really but it does make us software product owners.A title that needs to be coined now.
Job losses : come on, ask any ceo, there is so so much business always wanted to do and achieve but could not due to to lack of software delivary speed.That constraints is removed now.
However: Transition periods are confusing,chaotic and not time bound.That we need to bear.But a total and complete job losses for us,No way.
What i wrote in Jan 2026 new year:
by the time 2025 is closing and the question on will Coding LLMs/Agents/IDEs replace human programmer? gets aksed ,i am at ” It might actually” moment.
Few quarters before i was at ” may be lets see”.
Thats the amount of progress state of the art has made . Based on the report you read and the date of it ,some 40 percent of code and 256 billion lines of code has been outputted by models. Forget about the impact but such numbers means it is a large scale training and human verification that has already gone back into the models/to the labs.
With more focused optimizations from the AI LABs in the model architecture and deployments 2026 especially by plugging in some knowledge representation and knowledge priority/ranking might close the year 2026 on “Ah it happened”.
ps: there have been many shots taken at eliminating the programmer over last 4 decedes (really,its that old of a dream ). These attempts tried visuals, formatted config,drag and drop and even document based approaches. Additionally the design based approaches like annotation and injection also kept on happening.
But the “so called” ability to reason offered by LLMs is breaking past the totality barrier of code generation from specs . My best bet is models becoming runtime aware is what will be the last finishing touch to the masterpiece.
feb 2026 :
Most of the buzz on llm coding is about how fast and easy it was for a non tech person to write an app or software was.At times we hear personal experiences of using llm coding by old techies like me .
But we hardly hear anything from people who sell software itself as the commodity! So, the likes of android or spring or angular or chrome have a huge builtup of code complexity in them.They also have competing and conflicting features and a huge backlog of features they would have loved to implement yesterday.
The real and more believable metric of impact of llm coding will come from these places.If they are able to ship bigger feature sets faster,it would be the gold standard for productivity measurement around llm coding.
This also raises another question. When llm coding is so powerful why would we need their framework at all? would it not be easy to get your own curated framework based on your needs and use it. The picture is much darker for maintainers of smaller specialized libraries.
vibecoding or llm coding as i call it, is going to have its first evolutionary prey-victim soon. Cambrian explosion are beautiful and brutal at the same time.
By the time 2025 is closing and the question is whether Coding LLMs/Agents/IDEs replace human programmers? gets asked,i am at ” It might actually” moment.
Few quarters before i was at “maybe let’s see”.
Thats the amount of progress state of the art has made. Based on the report you read and the date of it ,some 40 percent of code and 256 billion lines of code have been outputted by models. Forget about the impact but such numbers mean it is a large scale training and human verification that has already gone back into the models/to the labs.
With more focused optimizations from the AI LABs in the model architecture and deployments 2026, especially by plugging in some knowledge representation and knowledge priority/rankin,g might close the year 2026 on “Ah it happened”.
ps: There have been many shots taken at eliminating the programmer over the last 4 decades (really, it’s that old of a dream ). These attempts tried visuals, formatted config, drag and drop and even document based approaches. Additionally, the design based approaches like annotation and injection, also kept on happening.
But the “so called” ability to reason offered by LLMs is breaking past the totality barrier of code generation from specs. My best bet is that models becoming runtime aware is what will be the last finishing touch to the masterpiece.
Sachin Dixit's Blog
Stay informed with curated content and the latest headlines, all delivered straight to your inbox. Subscribe now to stay ahead and never miss a beat!